Lead Instructor: Mian Ahmad Basit — Multan
LLM Fine-Tuning in Multan
Master LoRA, QLoRA, DPO, and GRPO to align and specialize open-weight models.
As Multan attracts more remote and outsourced engineering work, production AI skills open doors that generic coding knowledge doesn't.
Multan
Live cohort location
Live Weekly Classes
Practical, hands-on sessions
Certification
On completion
Freelance-Ready
Practical project focus
Before you scroll
Most people who see the curriculum don't finish reading it.
Drop your WhatsApp number and we'll send you the seat count for the next cohort — before it fills up.
Curriculum Breakdown
LLM Fine-Tuning — What You'll Learn in Multan
Learn the complete fine-tuning lifecycle — from dataset preparation and parameter-efficient adapters through preference alignment, quantization, and production-ready deployment of open-weight models. As Multan attracts more remote and outsourced engineering work, production AI skills open doors that generic coding knowledge doesn't.
Module 01
Data Preparation
- Instruction-pair and chat-format dataset construction
- ChatML and LLaMA-3 chat formatting
- Loss masking and dataset deduplication
- Synthetic instruction generation with Self-Instruct
- Data quality filtering pipelines
Module 02
PEFT & Adapters
- LoRA mathematics and rank/alpha selection
- QLoRA with NF4 quantization and paged optimizers
- DoRA magnitude-direction decomposition
- AdaLoRA adaptive rank allocation
- SFT pipeline design with FLAN and OpenHermes datasets
Module 03
Alignment & Deployment
- DPO, GRPO, and ORPO preference alignment
- RLHF, PPO, and reward model fundamentals
- GPTQ, AWQ, and FP8 quantization for inference
- LoRA adapter merging and multi-LoRA serving
- Deployment with vLLM, SGLang, and GGUF/llama.cpp
Outcome
Fine-tune, align, and deploy an open-weight LLM using production-grade techniques.
Program Instructor & Mentor
Learn LLM Fine-Tuning With Mian Ahmad Basit
Live mentorship for students in Multan and across Pakistan — practical training, not just theory.
Every module pairs structured theory with real, hands-on work — so students in Multan leave with skills they've actually practiced, not just watched.
Mian Ahmad Basit
Lead Instructor & Program Architect
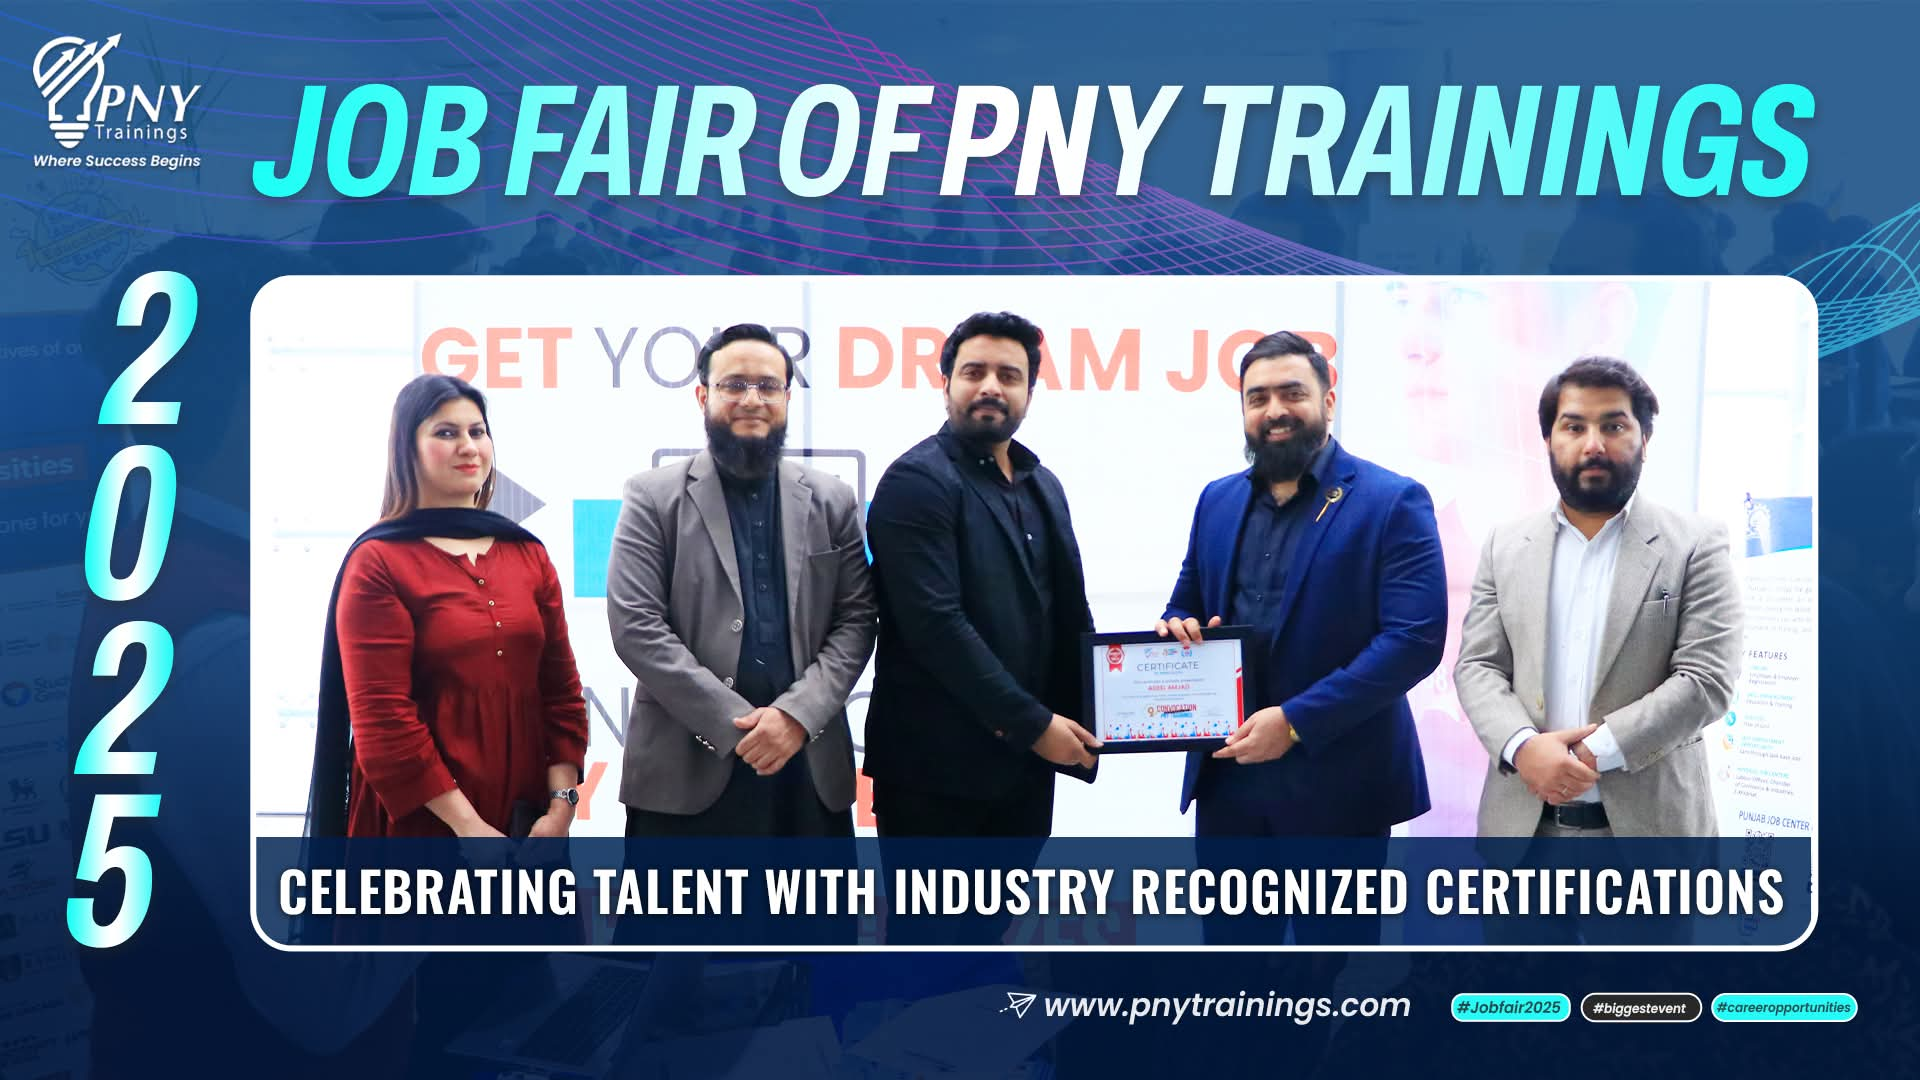
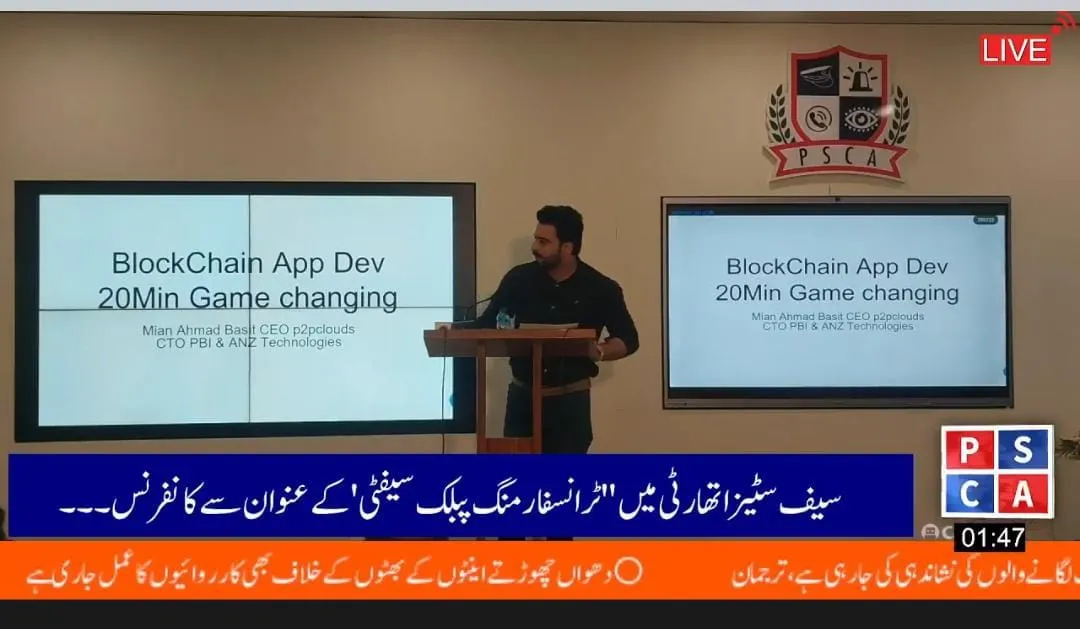
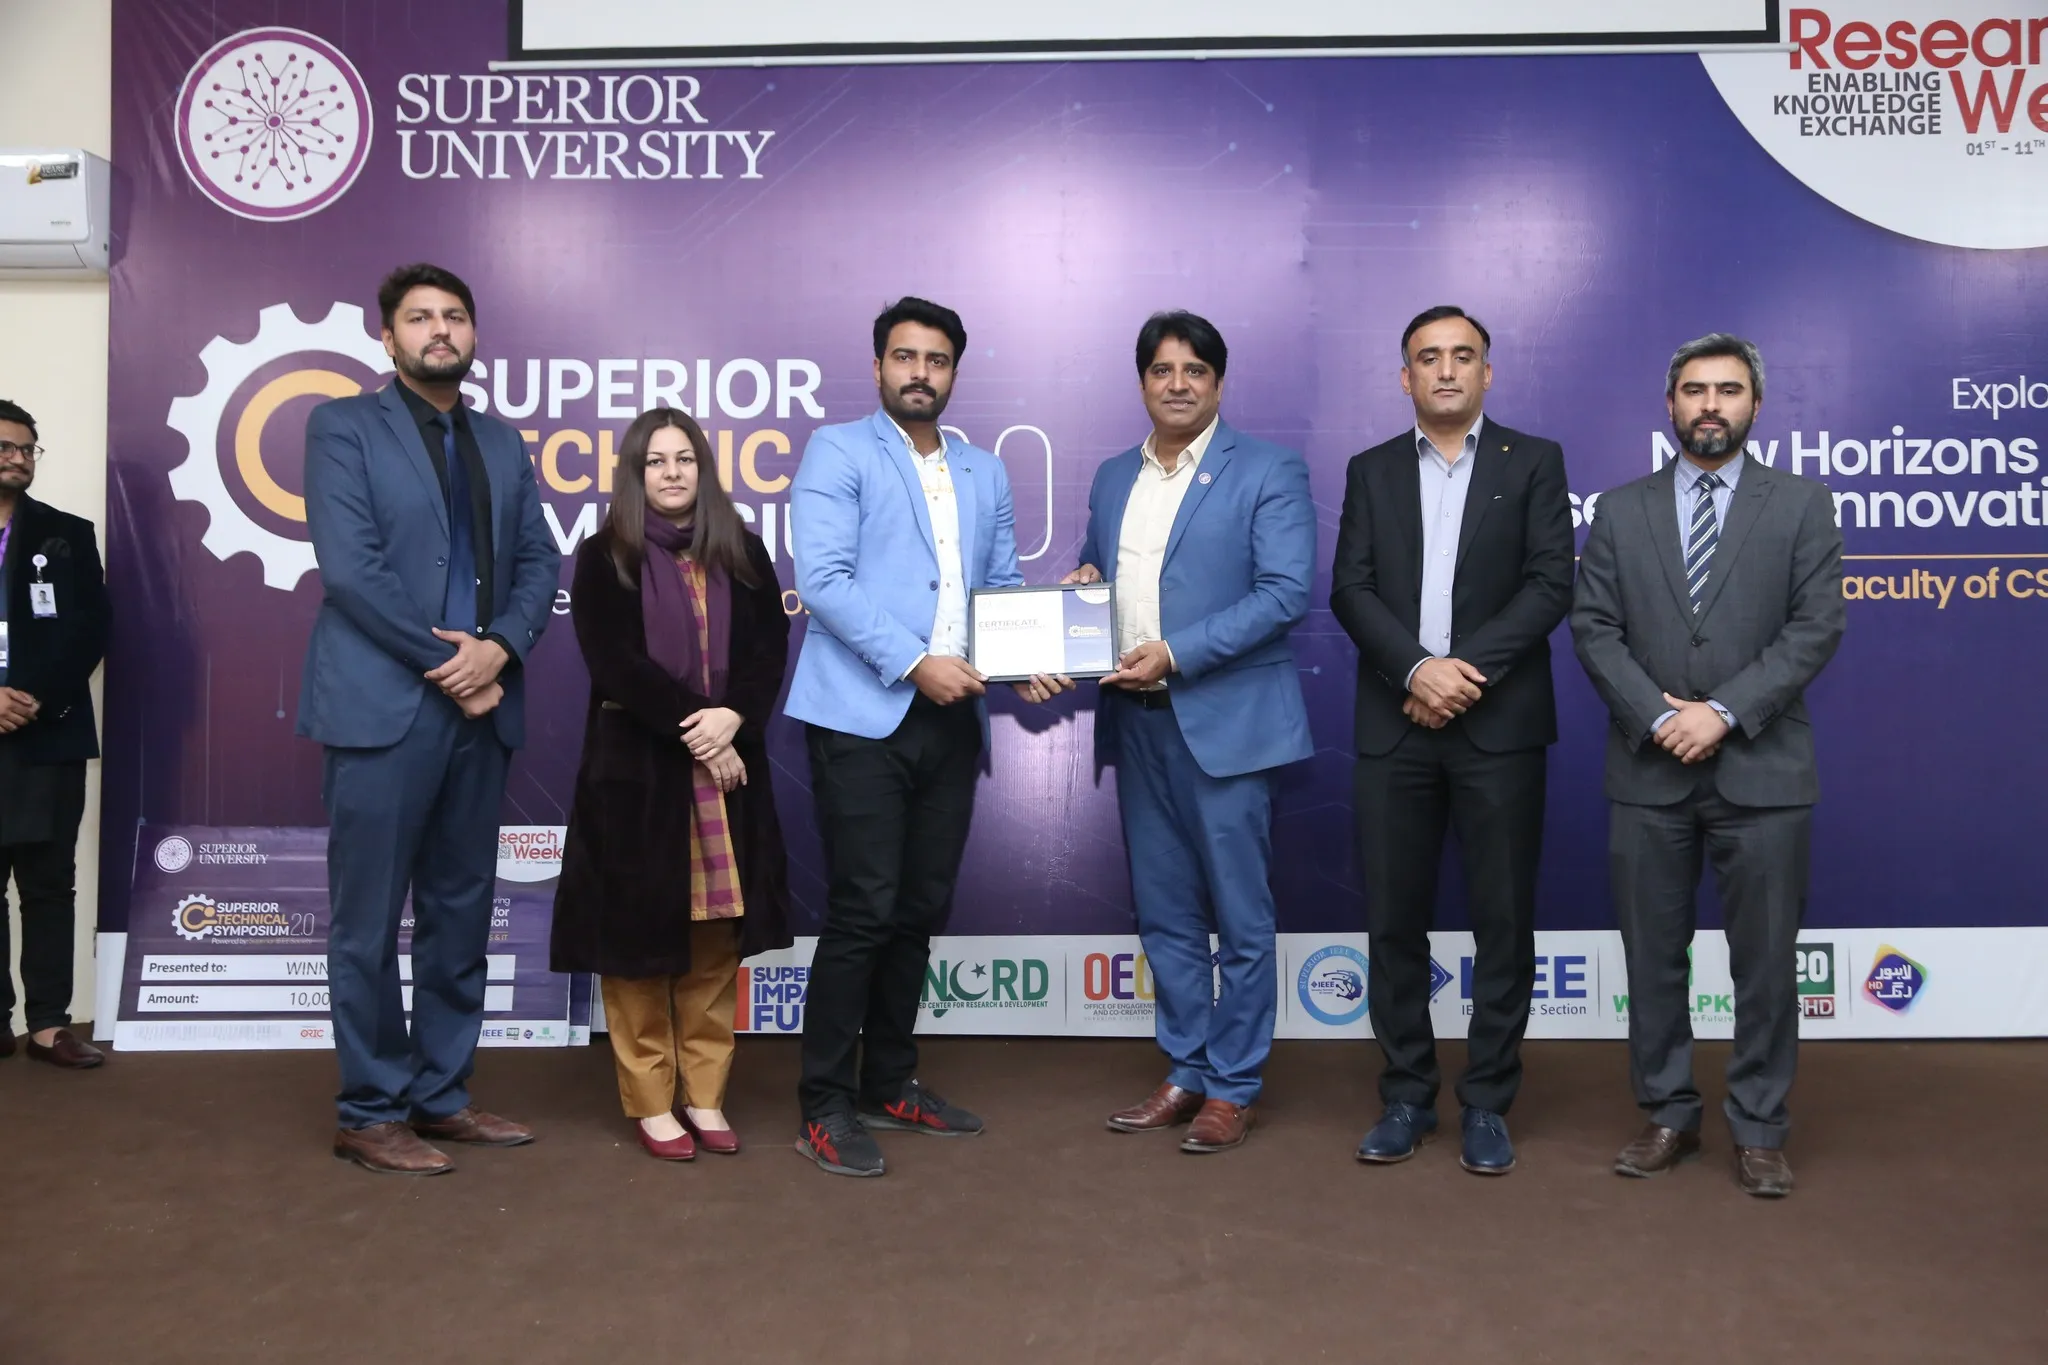
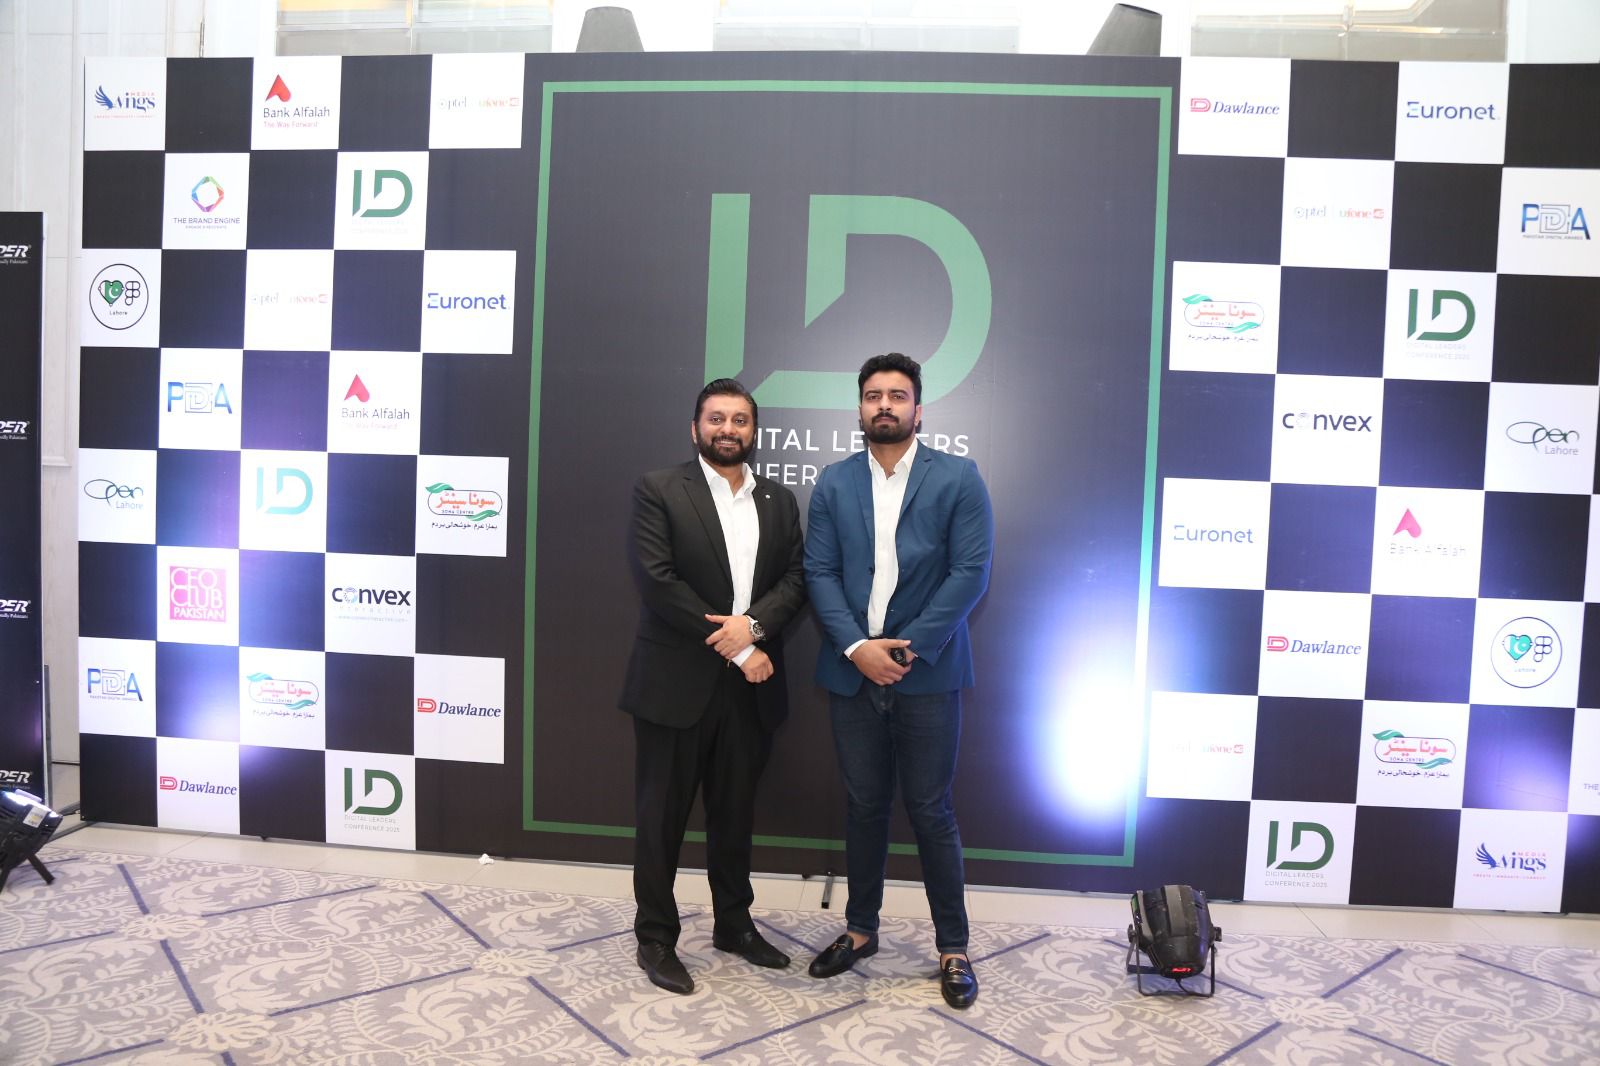
At Job Fair Of Pny Trainings
Live sessions, media appearances, and speaking engagements
Media / Talks / Featured
Watch & Learn
Featured talks, sessions, and insights from conferences, podcasts, and tech programs.
Frequently Asked Questions
LLM Fine-Tuning in Multan — FAQs
What hardware do I need?
QLoRA techniques covered in the course allow fine-tuning on a single consumer GPU — no enterprise hardware required.
Which tools does the course use?
Hugging Face TRL, PEFT, Unsloth, and Axolotl are all covered as fine-tuning frameworks.
Does this cover reasoning models like DeepSeek-R1?
The alignment section covers GRPO and rule-based rewards, the same techniques behind reasoning-model training.
Is this a standalone course or part of the full program?
This module is drawn from Mian Ahmad Basit's full-length program and can be taken as a focused track or as part of the complete curriculum.
Is this class online or in-person?
Classes run live online, so students anywhere in Pakistan — including this city — can join without relocating.
Lead Magnet Funnel
Apply for LLM Fine-Tuning in Multan
Share a few details and the team will follow up with the curriculum PDF, seat availability and next cohort dates.