Lead Instructor: Mian Ahmad Basit — Sialkot
Computer Vision & VLMs in Sialkot
Vision Transformers, CLIP, and Visual Language Models like LLaVA and Qwen-2-VL.
Remote AI engineering roles don't care where you're based — Sialkot-based engineers with real production skills can compete globally.
Sialkot
Live cohort location
Live Weekly Classes
Practical, hands-on sessions
Certification
On completion
Freelance-Ready
Practical project focus
Before you scroll
Most people who see the curriculum don't finish reading it.
Drop your WhatsApp number and we'll send you the seat count for the next cohort — before it fills up.
Curriculum Breakdown
Computer Vision & VLMs — What You'll Learn in Sialkot
Bridge classical computer vision into the multimodal era — Vision Transformer mechanics, contrastive vision-language models like CLIP and SigLIP, and how modern VLMs connect visual encoders to LLM backbones for multimodal reasoning. Remote AI engineering roles don't care where you're based — Sialkot-based engineers with real production skills can compete globally.
Module 01
Vision Transformers
- CNN-to-ViT conceptual bridge and inductive bias
- Patch embeddings, CLS token, and 2D positional encoding
- Visual self-attention and attention map interpretation
- CLIP and SigLIP contrastive vision-language pretraining
- DINO and DINOv2 self-supervised visual encoders
Module 02
Visual Language Models
- VLM architecture: encoder, projector, and LLM backbone
- LLaVA and Qwen-2-VL architecture walkthroughs
- MLP projectors and cross-attention aligners
- Vision-language feature space alignment
- Visual grounding for object and region understanding
Module 03
Multimodal Applications
- Document and layout understanding with VLMs
- Video and multi-frame document processing
- ColPali visual page retrieval for multimodal RAG
- Gemini Vision and multimodal API integration
- Building a practical visual-question-answering pipeline
Outcome
Explain and build the encoder-projector-LLM pipeline behind modern VLMs.
Program Instructor & Mentor
Learn Computer Vision & VLMs With Mian Ahmad Basit
Live mentorship for students in Sialkot and across Pakistan — practical training, not just theory.
Every module pairs structured theory with real, hands-on work — so students in Sialkot leave with skills they've actually practiced, not just watched.
Mian Ahmad Basit
Lead Instructor & Program Architect
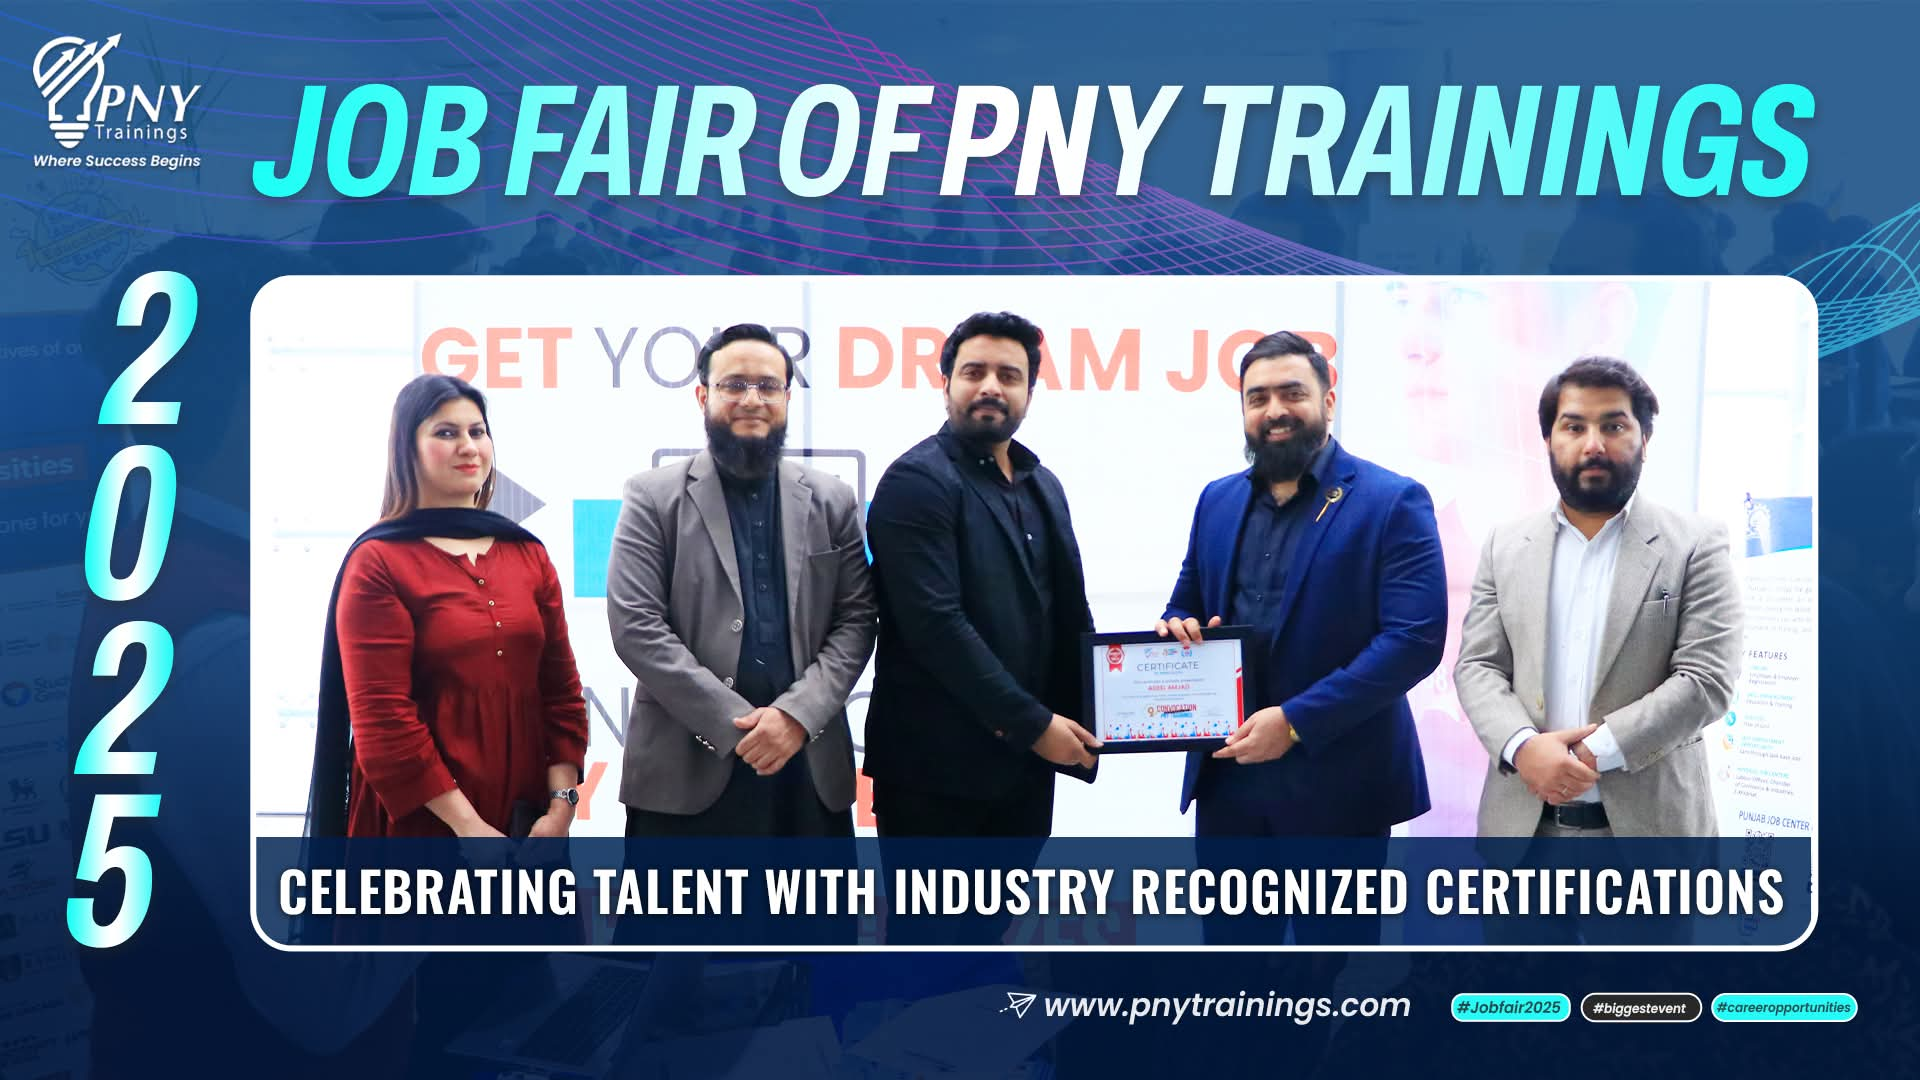
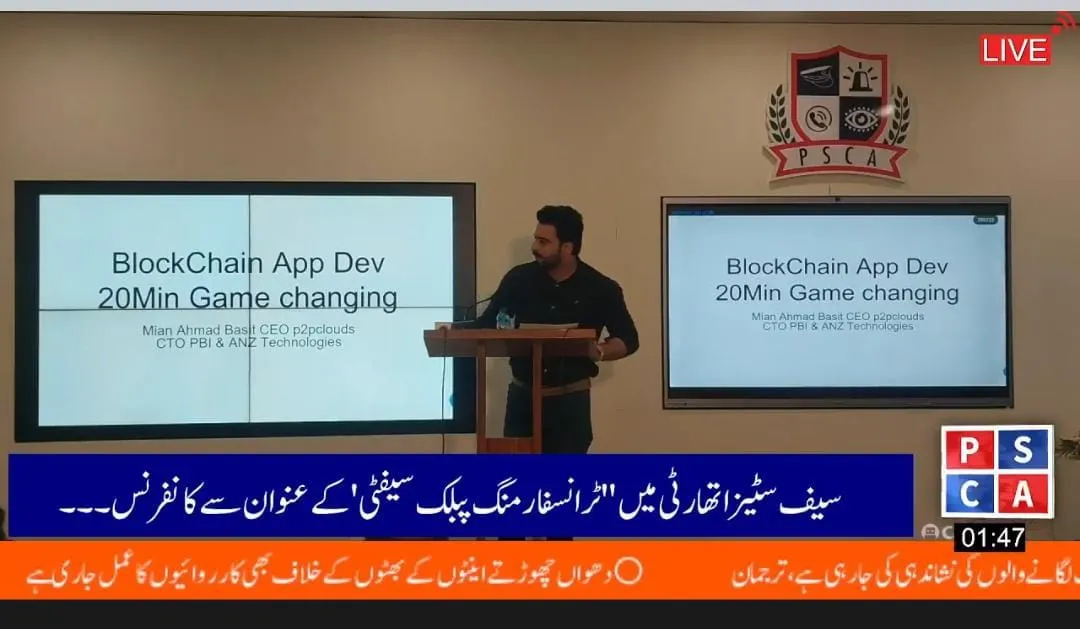
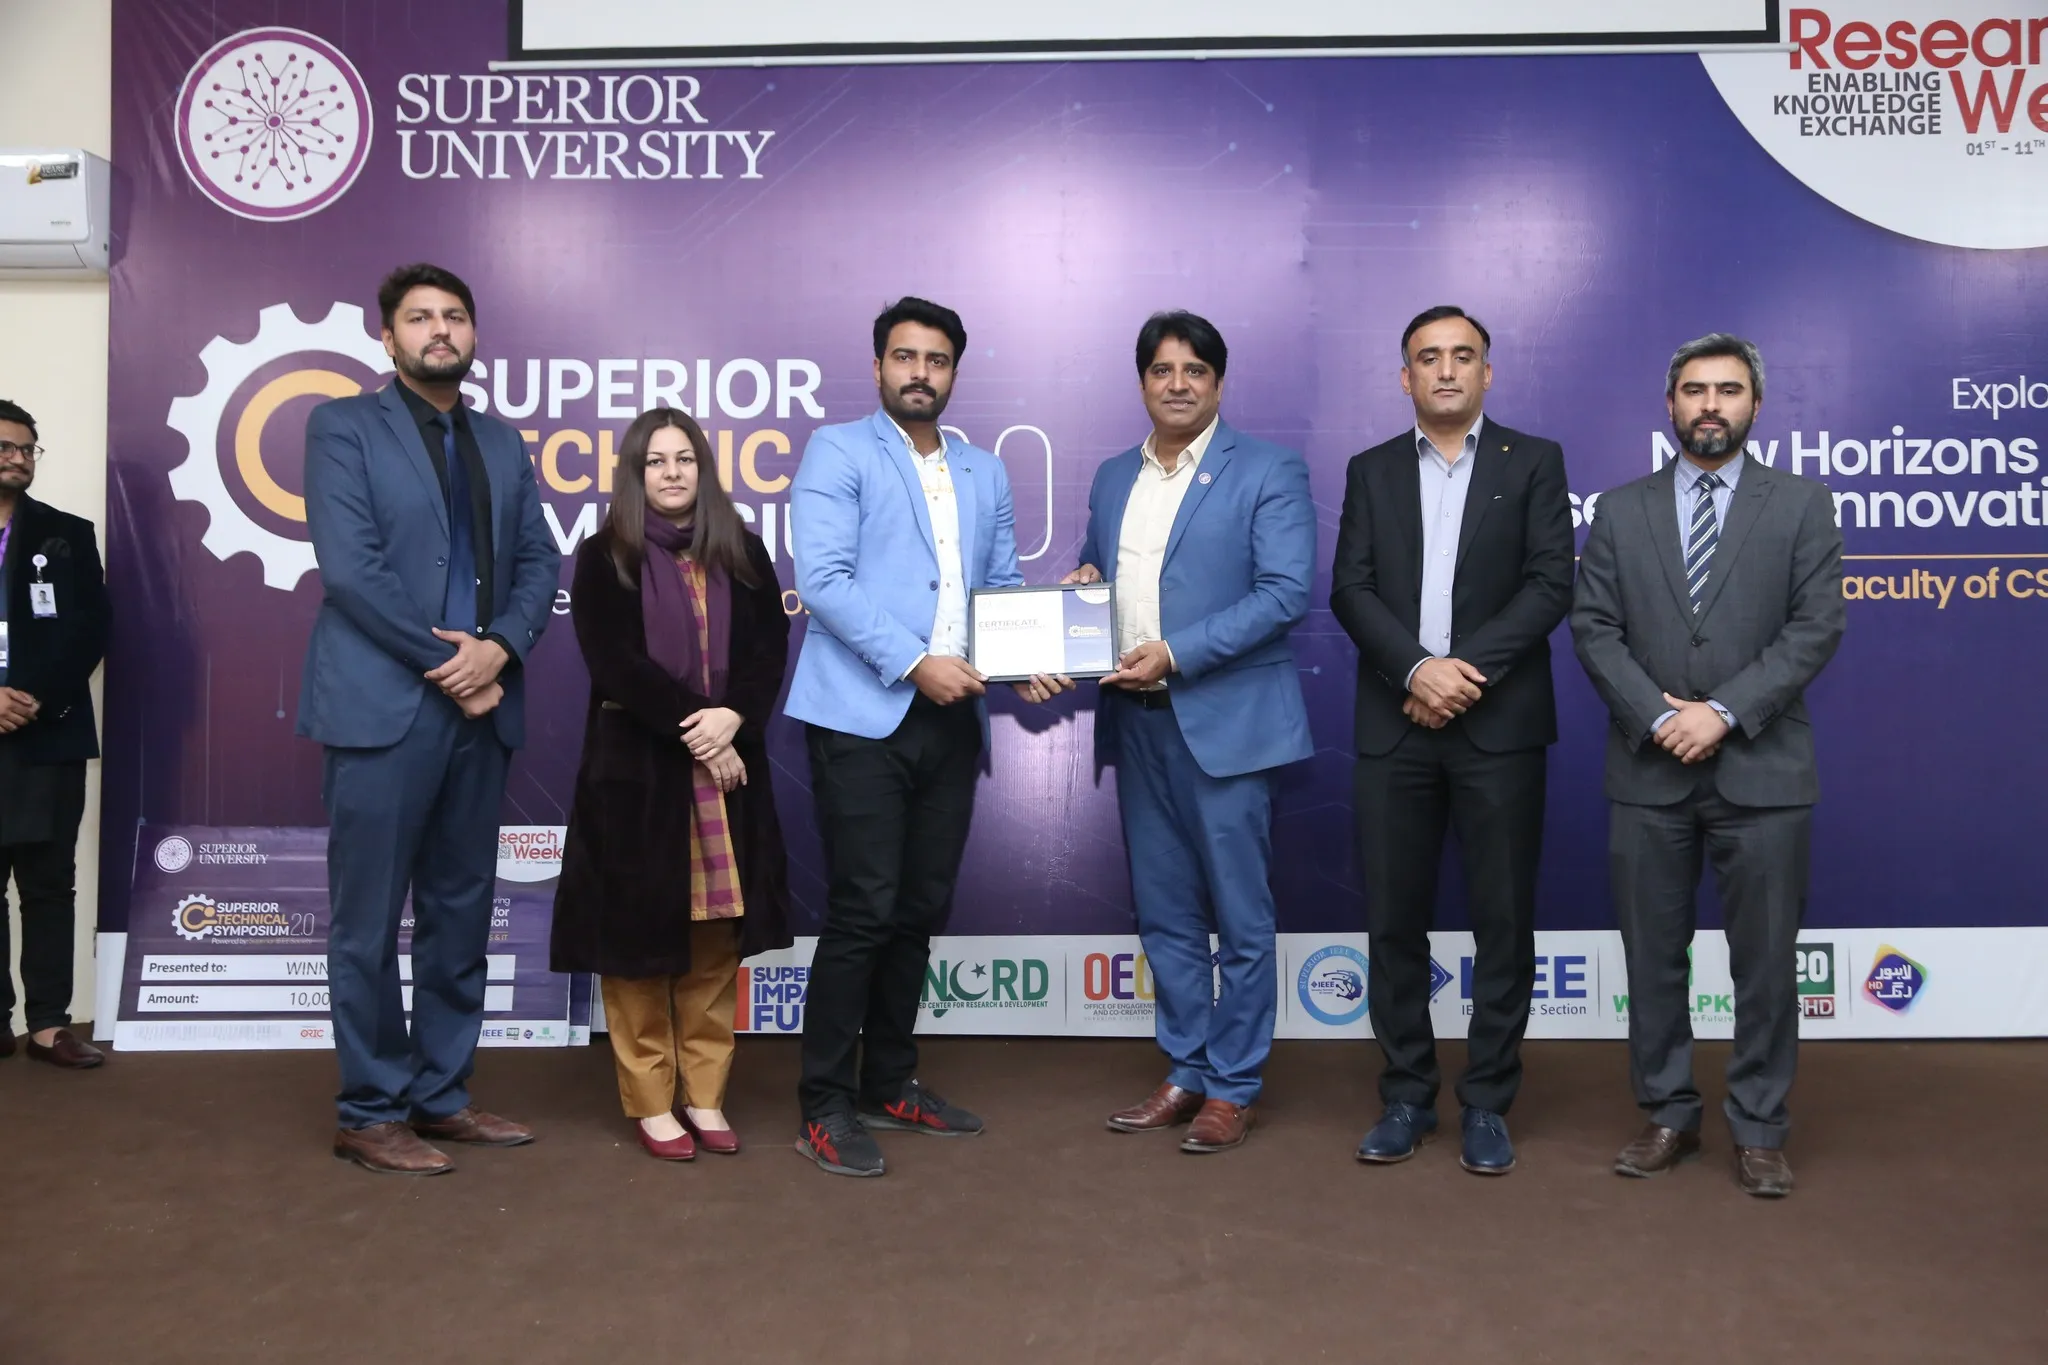
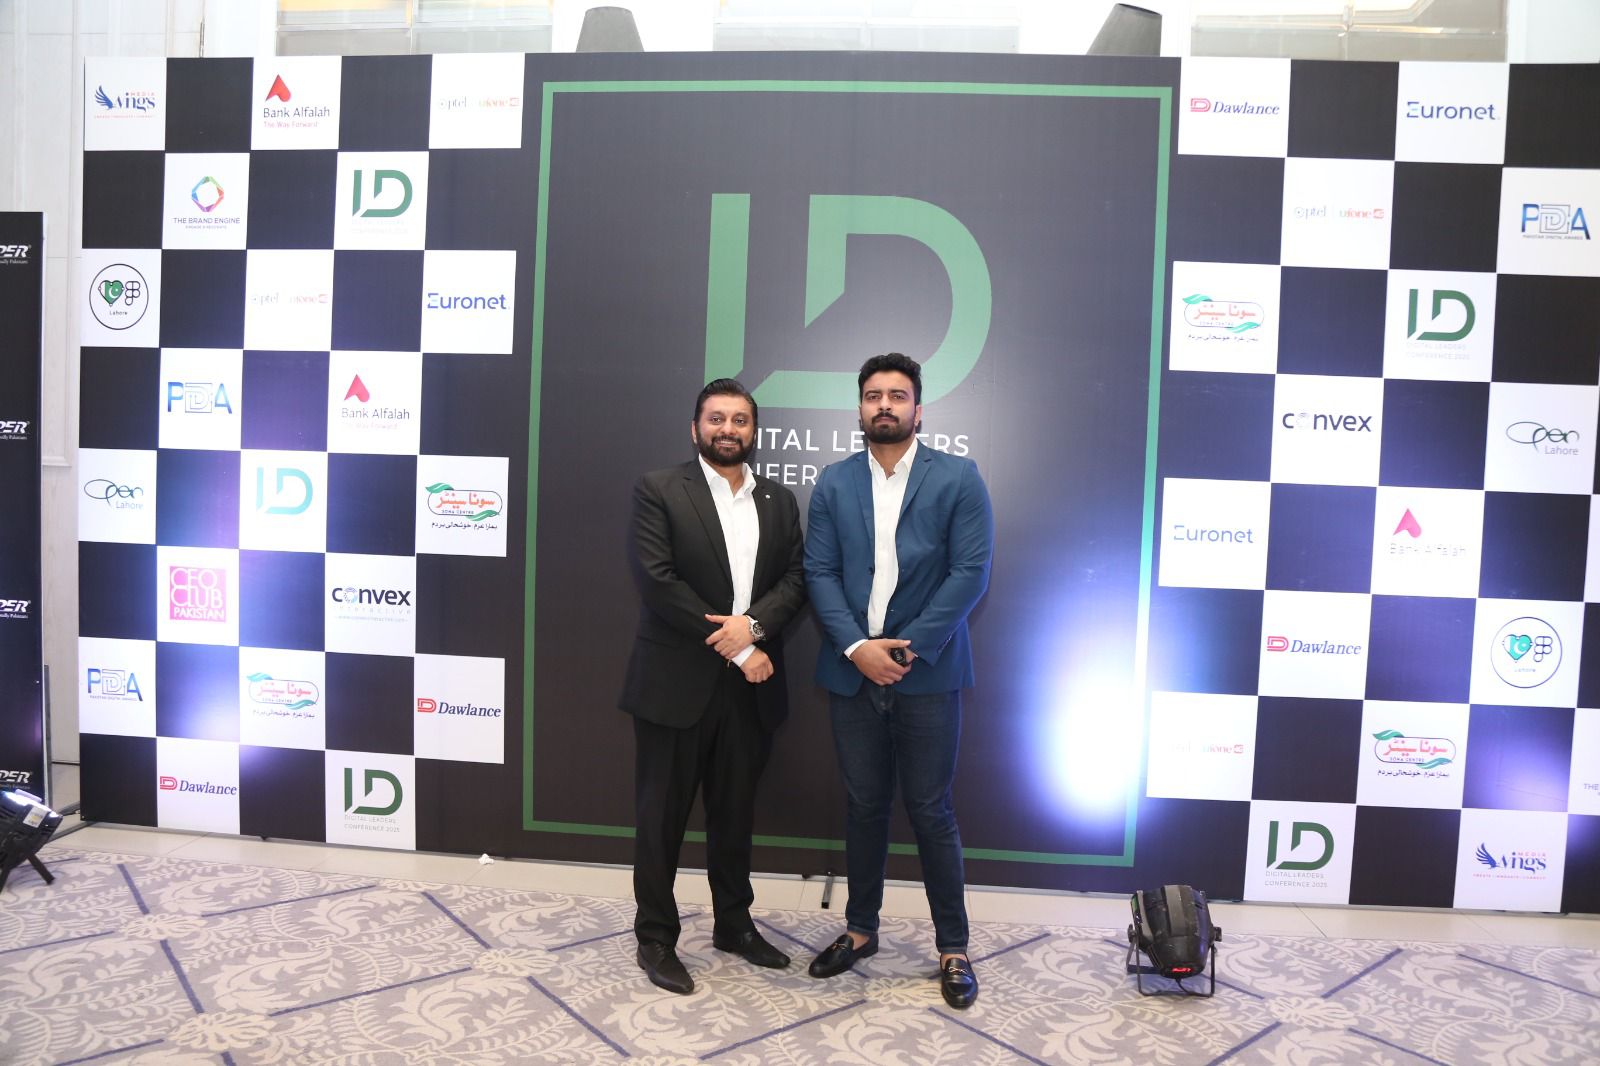
At Job Fair Of Pny Trainings
Live sessions, media appearances, and speaking engagements
Media / Talks / Featured
Watch & Learn
Featured talks, sessions, and insights from conferences, podcasts, and tech programs.
Frequently Asked Questions
Computer Vision & VLMs in Sialkot — FAQs
Is this only for image classification?
No — the focus is multimodal reasoning, visual grounding, and document/video understanding, not just classification.
Do I need computer vision experience first?
The module bridges from CNN concepts, so basic deep learning familiarity is enough to start.
Does this connect to the RAG module?
Yes — ColPali visual retrieval overlaps with multimodal RAG, and the two modules are designed to complement each other.
Is this a standalone course or part of the full program?
This module is drawn from Mian Ahmad Basit's full-length program and can be taken as a focused track or as part of the complete curriculum.
Is this class online or in-person?
Classes run live online, so students anywhere in Pakistan — including this city — can join without relocating.
Lead Magnet Funnel
Apply for Computer Vision & VLMs in Sialkot
Share a few details and the team will follow up with the curriculum PDF, seat availability and next cohort dates.